Physical AI
Validated and reliable robot policies.
Every motion is traced to what the policy sees.
Works on open-weight policies.
Built by researchers from Fraunhofer HHI.
Demo
From memorisation to generalisation.
In training, the plate always stood in the same spot, so the robot learned to focus on its location instead of looking at the plate. When we move the plate, it puts the bowl where the plate used to be. Layerwise shows it hardly looks at the plate. After retraining, it does.
Memorisation failure
Generalisation
Offer
Shows what your policy relies on and which runs fail.
Included in every deployment
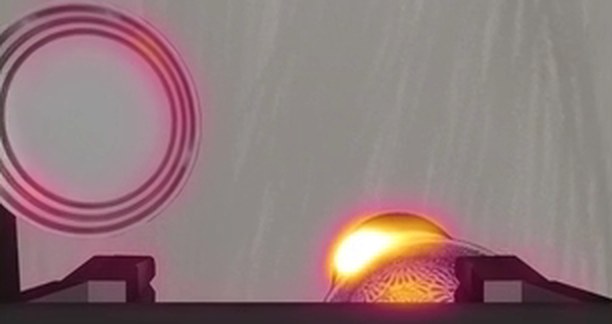
Relevance maps
Layerwise highlights the inputs that drive each motion.
- For each camera and each phase of the task
- Shown on your own logged rollouts
Failure detection
Layerwise reads the policy's internals and flags the runs that fail.
- Shows which runs to review
- Tested on tasks never seen in training
Optional service
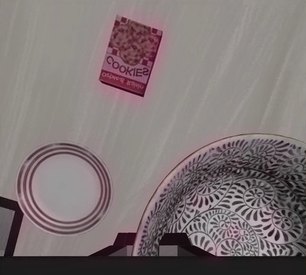
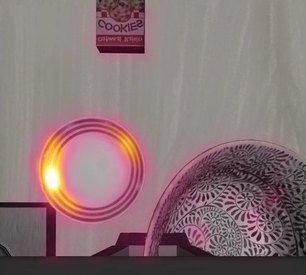
Policy fine-tuning
We retrain your open-weight policy on the demonstrations it was missing.
- Looks at the right objects after retraining
Proof
Results on three open robot policies.
Measured in simulation on OpenVLA-OFT, π0.5 and SmolVLA, against standard and published baselines.
Relevance maps
1st of 14
Most faithful relevance map among 14 attribution methods
OpenVLA-OFT on LIBERO
Faithfulness · three of the 13 others
Failure detection
0.90
AUROC for predicting a failing run on tasks never seen in training
SmolVLA on LIBERO
Same test, other approaches
AUROC, 0.5 is chance. Best variant of each approach.
Reliable policy
+62%
More scenes with a moved plate solved after retraining on our demonstrations
OpenVLA-OFT on LIBERO · π0.5 gains as much
OpenVLA-OFT
π0.5
Pilot
Your policy, validated in eight weeks.
Together with our scientists, we explain your policy, set up monitoring and fix what it gets wrong.
- Week 1
Connect
We set up your checkpoint and replay your logged rollouts.
- Weeks 2 to 5
Diagnose and report
We show which inputs drive your policy, and which runs fail. You decide on rollout.
- Weeks 6 to 8
Fine-tune, optional
A retrained policy with measured results.
- After week 8
Ongoing support
In production, and when your tasks or your robot change.
What we need from you
One checkpoint of an open-weight policy
Such as OpenVLA-OFT or π0.5.
Logged rollouts of one task
From your own robot.
One engineer as a contact
For access and questions on the setup.
What you get
What the policy looks at
On your own rollouts.
A list of memorised motions
A retrained policy, optional
With the measured result.
Let's validate your policy now.
Tell us which policy you run and which tasks your robot should do.
Get in touch